What to know
- CoreWeave announced availability of Vera Rubin NVL72 capacity.
- Cognition reported early inference gains on a specified workload.
- Hardware throughput does not directly measure successful agent tasks.
New capacity reaches early customers
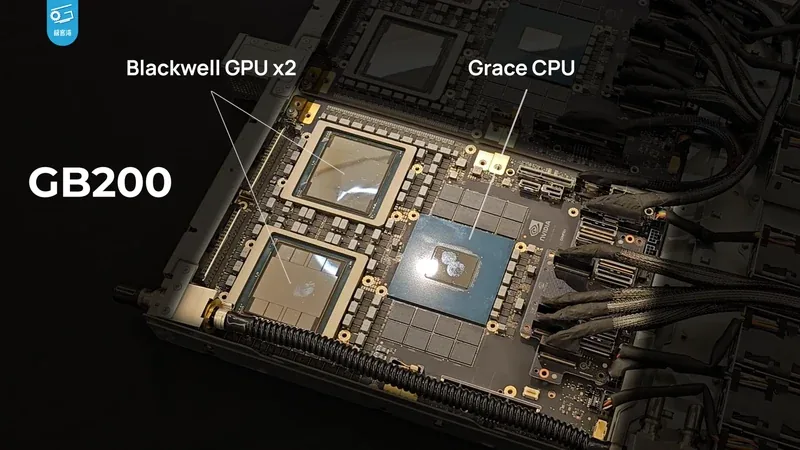
NVIDIA said on September 30 that CoreWeave had made Vera Rubin NVL72 available on its cloud platform. The account describes Cognition testing the system for coding-agent inference and reporting up to 4.8 times the token throughput of a GB200 NVL72 baseline on its SWE-2 workload.
These are early workload-specific results reported by the participating companies. They establish a concrete deployment and test, but they do not provide a universal comparison for every model or application. NVIDIA also describes work on agent execution environments and a connected training workflow, placing the launch in a broader infrastructure offering.
Source: NVIDIA: CoreWeave agent infrastructure and Vera Rubin
Throughput answers one capacity question
Token throughput is relevant when many requests compete for compute. It helps describe how much model output a system can serve over time. An individual user, however, may care more about the delay before a useful answer or the time until an agent finishes a task. Increasing aggregate output does not automatically improve each of those measures by the same amount.
A coding workload also spends time outside inference. It may compile software, retrieve dependencies, execute tests or wait for a service. A system comparison should identify whether those steps run on comparable infrastructure and whether they are included in the reported result. Otherwise, a hardware gain can be mistaken for a full application improvement.
The number of accepted results matters as well. More simultaneous attempts can produce more output without increasing the share of tasks solved correctly. A buyer can avoid that ambiguity by tracking completed work at a fixed quality standard, together with latency, resource consumption and the review required afterward.
A connected platform has trade-offs
Byte Watchr’s analysis is that keeping training, evaluation and deployment close together can reduce coordination work. It can also make the platform responsible for a larger portion of the operating process. Buyers should examine how data and evaluation records move between stages and how those records can be exported if the deployment changes.
Capacity planning should include the expected mix of workloads. A service optimized for long, concurrent coding sessions may be an unsuitable reference for short interactive queries. Peak demand, region availability and recovery arrangements can matter more to a particular customer than the largest published throughput figure.
The CoreWeave announcement supplies evidence that the new hardware is entering customer use. The next procurement step is a comparable evaluation with the intended model, task distribution and service target. That is how a buyer can translate an early infrastructure result into a defensible decision about cost and delivery, while preserving the limits of what the launch data actually demonstrates.
Sources & further reading
Factual statements are grounded in the linked material. Interpretation and illustrative examples are Byte Watchr analysis. Vendor claims are identified as claims, rather than independent testing.
The event date records the source announcement or documented operation. The coverage edition groups recent developments and is separate from the publication date. Actual publication is recorded above.
Corrections policy · About this byline