What to know
- Model size alone does not determine usefulness for a specific task.
- Smaller deployments still need quality, privacy and security checks.
- A focused workflow can be more valuable than broad conversational ability.
Start with the job, not the parameter count
A smaller model can be an attractive choice when an application needs predictable latency, constrained memory use or local execution. It may perform well on a narrow task even if it is less capable across a broad evaluation. The word smaller describes a resource characteristic, not a universal quality level.
A device that classifies a limited set of equipment alerts does not need the same conversational range as a general research assistant. Defining the task precisely makes it possible to test whether a compact model is sufficient. Without that definition, teams can mistake a lower operating cost for equivalent capability.
Where the resource savings appear
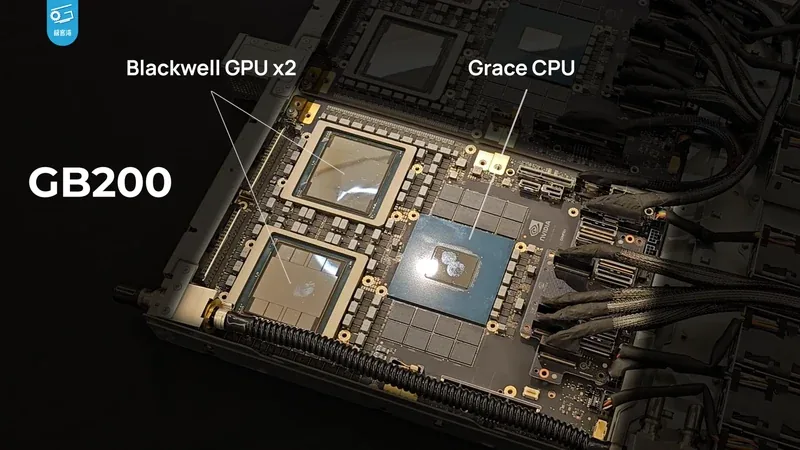
The memory needed to hold model parameters is only part of deployment. The system also needs runtime state, context storage and supporting application resources. GPU performance guidance is useful here because it separates compute work from memory movement and other constraints.
A compact model may fit on a device that cannot host a larger one. It may also leave more room for concurrent work. Actual gains depend on numerical precision, software support, sequence length and the hardware in use, so measure the finished application rather than extrapolating from a model file’s size.
Specialization introduces boundaries
A narrow model may be reliable on familiar inputs and brittle on inputs outside its training or tuning distribution. A helpdesk classifier trained on one organization’s ticket labels may not generalize to a different product or language. A smooth response can conceal that mismatch.
Evaluate unusual, ambiguous and out-of-scope inputs. The system should have a path to defer or escalate rather than forcing every request into a known category. Record which tasks it is approved to perform, and make changes to that scope an explicit deployment decision.
Local does not automatically mean private
Running a model on a device can reduce the need to transmit prompts to a remote service. The surrounding application may still collect telemetry, synchronize documents or use cloud fallback. Security depends on the complete data flow, including logs and update mechanisms.
Ask where inputs, outputs and error reports are stored. Confirm how model files are authenticated and updated. A local model loaded from an untrusted source can introduce a supply-chain problem even when its normal operation keeps user data on the device.
Build a portfolio, not a slogan
Some applications can route routine work to a smaller model and escalate difficult cases to a stronger system. That can improve economics, but the routing decision becomes another component to evaluate. A poor confidence estimate can send the hardest requests to the least suitable model.
Choose a compact model when it meets an explicit quality threshold on the intended workload. Treat the savings as a benefit of a proven design, rather than the reason to lower the definition of success.
Sources & further reading
Factual statements are grounded in the linked material. Interpretation and illustrative examples are Byte Watchr analysis. Vendor claims are identified as claims, rather than independent testing.
This article belongs to Byte Watchr’s launch collection. The edition date organizes evergreen coverage and does not imply historical publication. Actual publication is recorded above.
Corrections policy · About this byline