Artificial Intelligence / News analysis
GitHub releases ReviewBench for comparing AI code reviewers
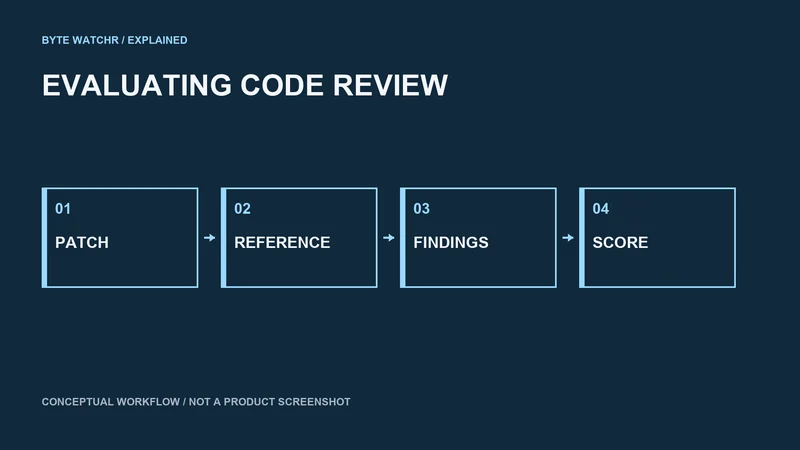
The research preview uses 219 public pull requests and separates existing reference findings from new issues identified during evaluation.
THE TOPIC FILE
A capable demonstration is a starting point. Explore benchmarks, realistic testing, missing-answer behavior and the operational measures that help distinguish useful AI from convincing mistakes.
Artificial Intelligence / News analysis
The research preview uses 219 public pull requests and separates existing reference findings from new issues identified during evaluation.
Artificial Intelligence / News analysis
The 3.35-billion-parameter research model emphasizes reasoning in the requested language, with noncommercial licensing and company-reported evaluation results.
Artificial Intelligence / News analysis
REST and GraphQL review requests give teams more control over automation. Review value still depends on which findings improve the code and how much checking they require.
Technology / News analysis
The reported acceleration targets model output speed. Its effect on a complete agent task depends on the time spent using tools, testing and waiting.
Artificial Intelligence / News analysis
Google’s phased release makes access, evaluation and operational controls central to the next stage of its frontier model rollout.
Artificial Intelligence / News analysis
Clef and Clef-flash target bounded classifications inside software workflows, where output consistency and the cost of a wrong decision matter.
Artificial Intelligence / News analysis
The new audio models separate live speech recognition from speech generation, giving developers distinct choices for latency, language coverage and cost.
Software / News analysis
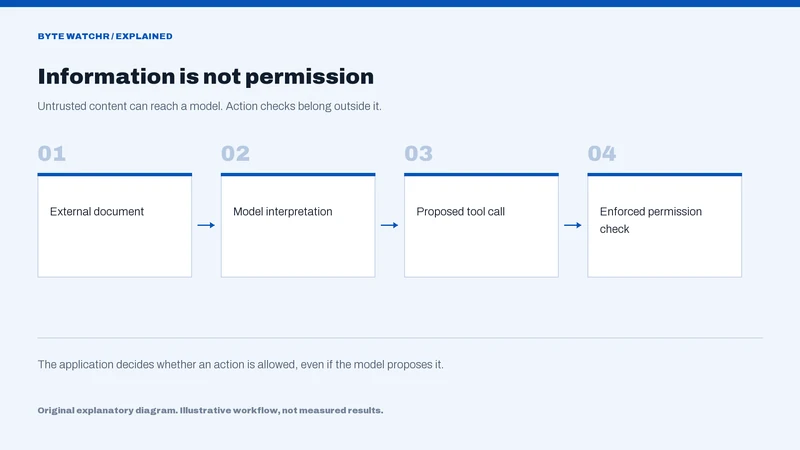
Native image embeddings and OCR extend the managed retrieval service, while document permissions and answer verification remain application responsibilities.
Technology / News analysis
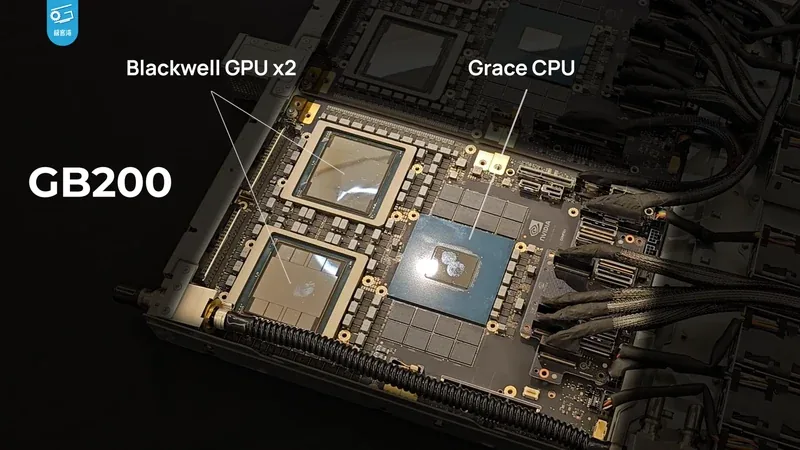
Early customer testing links the new infrastructure to coding-agent inference, while throughput, concurrency and completed-task performance remain distinct measures.
Technology / News analysis
A new account of NASA’s work describes natural-language access to Earth science data and a prototype for flight-controller support, with human decisions remaining central.
AI Security / News analysis
The internal system tests candidate vulnerabilities against running environments before sending verified findings to product teams, addressing a central weakness of automated reporting.
Software / News analysis
New median and tail-latency fields distinguish the wait for a first review from later review and merge delays, with important limits on which pull requests count.